One of the most frequent conversations we have with new clients starts the same way: “We have a working prototype. We expected it would take 2-4 weeks to put it into production. It’s been 4 months.”
This is almost universal. The gap between “it works on my laptop” and “it works reliably in production for real users” is much wider than most teams anticipate. Here’s an honest breakdown of why.
The Prototype Is Usually 10% of the Work
A prototype demonstrates that the AI approach works for the use case. It typically doesn’t have:
- Error handling for unexpected inputs or API failures
- Authentication, authorization, or multi-tenancy
- Monitoring, logging, or alerting
- Auto-scaling infrastructure
- Automated testing or CI/CD
- Data privacy or compliance considerations
- Rate limiting or cost management
- A performant database designed for production query patterns
- API versioning and backwards compatibility
Each of these items is real engineering work. None of it is glamorous, but all of it is necessary. Our AI production readiness checklist turns this list into launch criteria you can check off.
A More Realistic Timeline
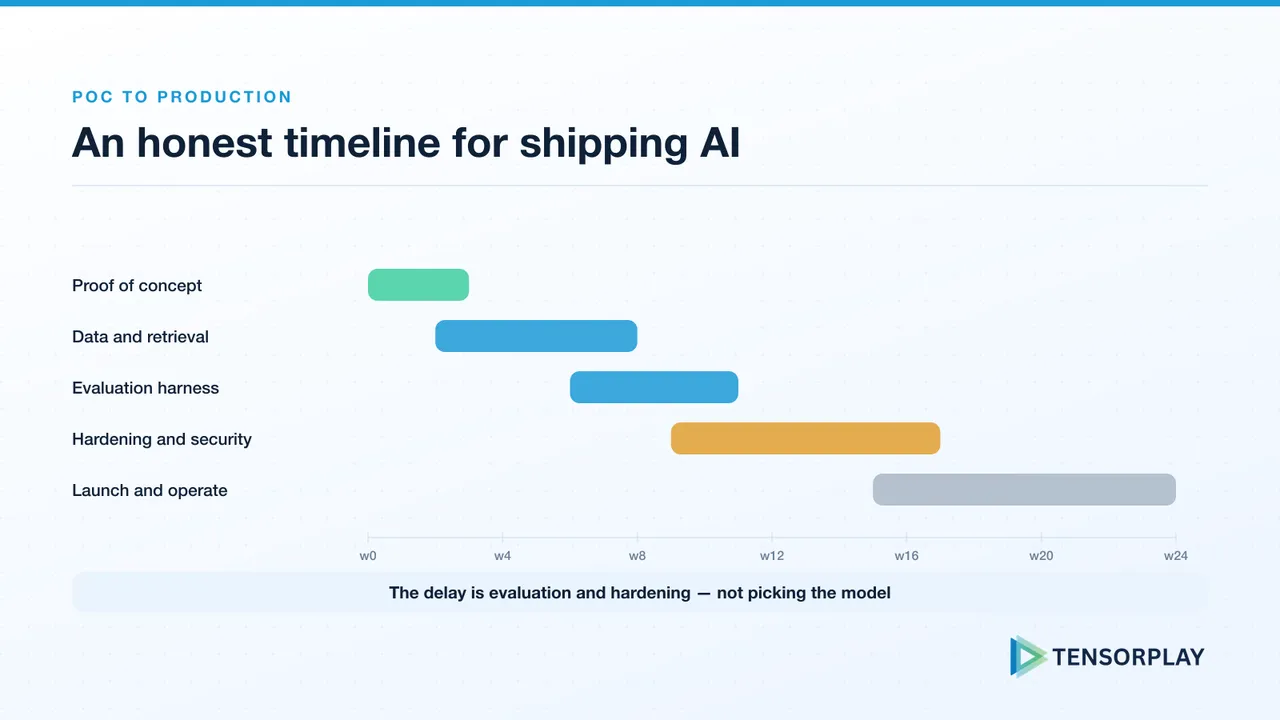
Here’s a rough breakdown for a typical AI application going from a solid PoC to production:
Weeks 1-2: Architecture & Infrastructure
Design the production architecture, set up cloud environments, establish CI/CD pipelines, choose and integrate the vector store, design the data model.
Weeks 3-5: Core Engineering
Refactor the PoC code into a production service — proper error handling, structured logging, API design, authentication layer, streaming support.
Weeks 6-8: Quality & Reliability
Build the evaluation suite using an LLM evaluation framework, run systematic prompt evaluation, implement monitoring and alerting, load testing and performance optimization.
Weeks 9-10: Security & Compliance
Security review against an AI-specific threat model, data privacy audit, access control implementation, penetration testing if required.
Weeks 11-12: Deployment & Rollout
Staged rollout with feature flags, monitoring ramp-up, documentation, and team training.
For complex multi-agent or multi-modal systems, add 4-8 weeks to each phase.
How to Move Faster
The fastest teams we work with share some common traits:
- They invest in a proper architecture design phase before writing code
- They build evaluation infrastructure early, not after everything is “done”
- They deploy a minimal production slice to real users early and iterate
The slowest teams underestimate the non-model work and try to shortcut the infrastructure phase — which consistently leads to painful rewrites.
If you’re planning an AI productionisation project and want a realistic timeline estimate for your specific case, talk to Tensorplay about your roadmap.