Vector databases are now a core piece of production AI infrastructure. Whether you’re building a RAG pipeline, a semantic search engine, or a recommendation system, you need somewhere to store and efficiently retrieve high-dimensional embeddings. If you are still deciding whether retrieval is the right approach at all, start with RAG vs fine-tuning.
The market has exploded with options. Here’s how we evaluate them for client projects.
What You’re Actually Optimizing For
Before comparing databases, clarify your requirements:
- Query throughput: How many vector searches per second do you need?
- Dataset size: How many vectors will you store — millions? Billions?
- Latency requirements: Is 50ms acceptable, or do you need under 10ms?
- Metadata filtering: Do you need to filter by metadata alongside vector similarity? For multi-tenant data this is also a security control: permission filters at retrieval time are central to any AI application threat model.
- Hosting preference: Managed cloud, self-hosted, or embedded?
The Main Contenders
Pinecone
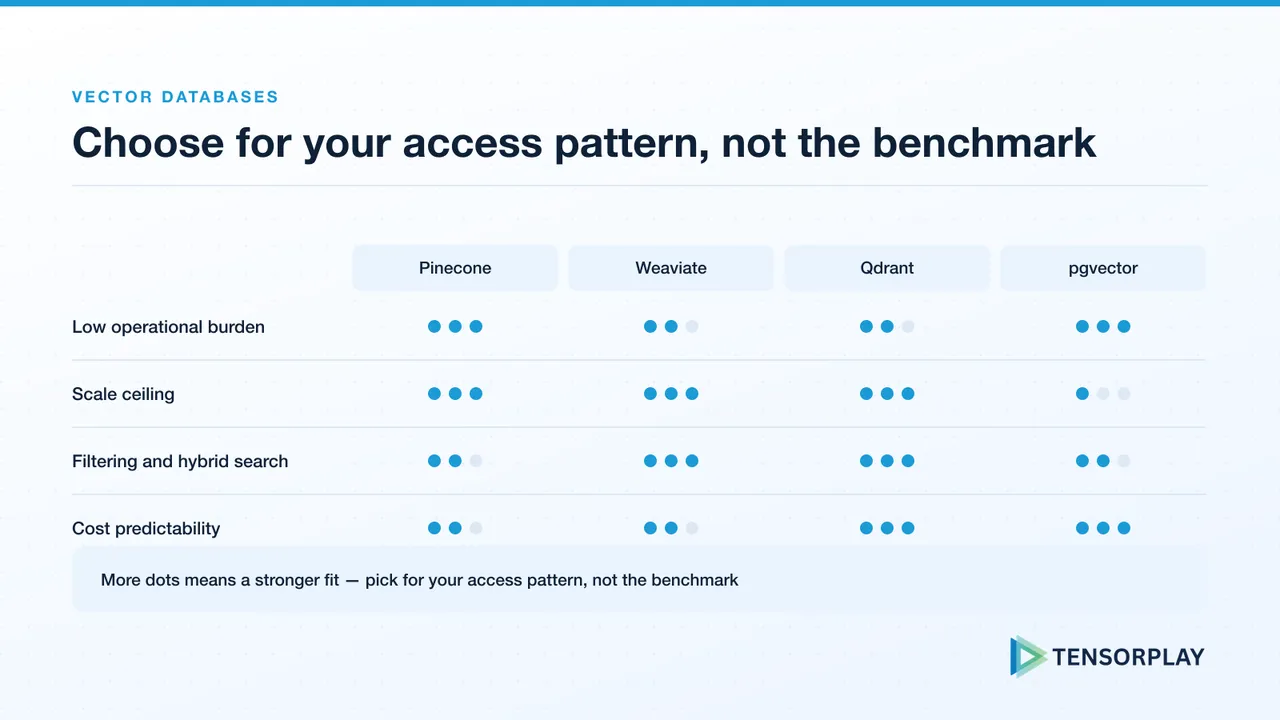
Fully managed, serverless, zero infrastructure management. Excellent developer experience and reliable performance. The trade-off: higher cost at scale and limited customization. Best for teams that want to move fast and aren’t yet at a scale where infrastructure costs are a concern.
Weaviate
Open-source and self-hostable, but also offers a managed cloud. Strong built-in support for hybrid search (combining dense and sparse retrieval), a native GraphQL API, and module-based architecture for embedding generation. Good choice for teams needing more control over their stack.
Qdrant
Rust-based, extremely fast, excellent performance per dollar. Supports payload (metadata) filtering efficiently. Great for high-throughput use cases. Self-hosted with a managed cloud option. Increasingly our go-to for performance-critical projects.
pgvector
A PostgreSQL extension that adds vector similarity search. If your data is already in Postgres, this is often the pragmatic choice — one less system to manage, ACID transactions, familiar tooling. Performance lags behind dedicated vector databases at very large scale, but is totally fine up to tens of millions of vectors.
Chroma
Excellent for local development and prototyping. Not our recommendation for production at significant scale, but a fantastic tool for getting a RAG proof-of-concept running quickly.
Our Recommendation Matrix
| Use Case |
Our Pick |
| Fast prototype / low volume |
Chroma or pgvector |
| Already on Postgres, < 10M vectors |
pgvector |
| Managed cloud, moving fast |
Pinecone |
| Self-hosted, high performance |
Qdrant |
| Hybrid search requirements |
Weaviate |
| Billion-scale |
Weaviate or Qdrant (custom deployment) |
Choosing the right vector store is one of the first architectural decisions in any RAG project, and getting it wrong is expensive to fix later. It is also only one part of retrieval quality: chunking, freshness and access control matter just as much, as covered in RAG reliability in production. If you’d like a recommendation tailored to your specific use case, talk to Tensorplay about your retrieval architecture.