One of the most common questions we get from engineering teams is: “Should we fine-tune our model or use RAG?” The honest answer is: it depends on what problem you’re actually trying to solve.
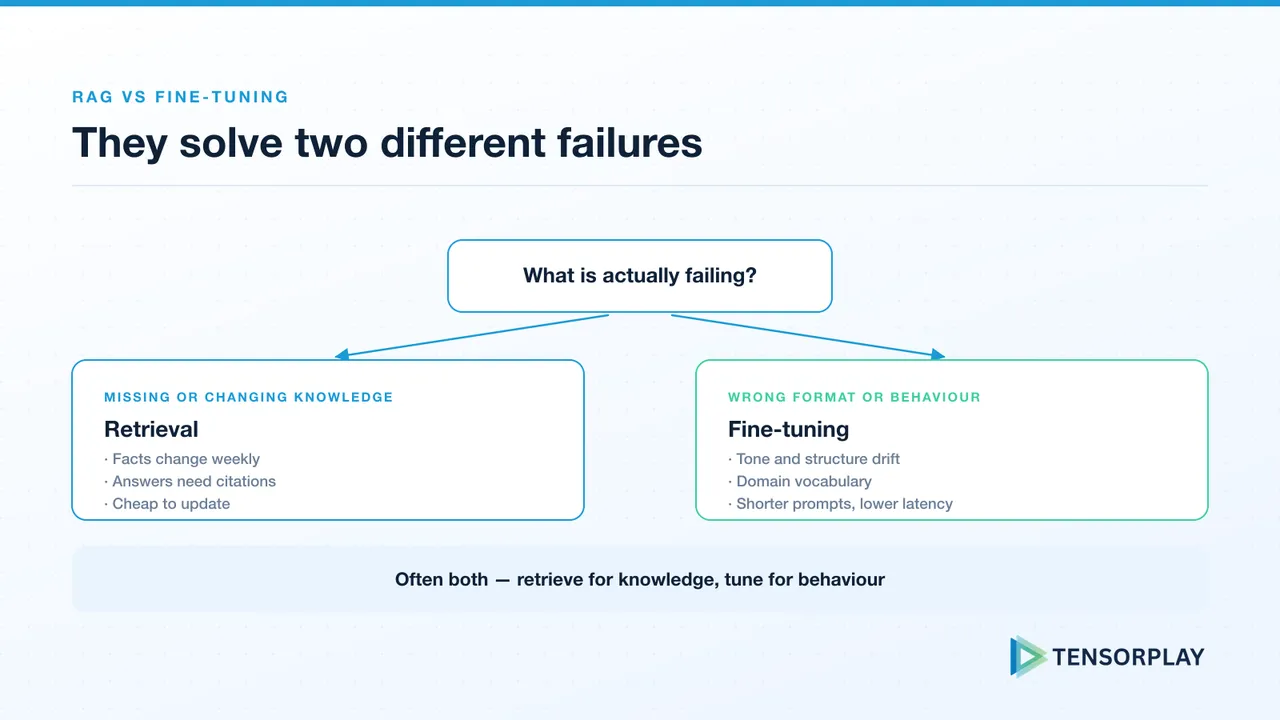
Both techniques have their place — but choosing the wrong one will cost you weeks of wasted engineering effort. Here’s how we think about it at Tensorplay.
What is RAG?
Retrieval-Augmented Generation (RAG) is a technique where you inject relevant documents or data into the model’s context window at inference time. The model doesn’t “learn” anything new — it uses its existing reasoning capabilities to answer questions using the documents you’ve provided. Answer quality depends heavily on that retrieval step and the store behind it; see our guide to choosing a vector database.
RAG is the right choice when:
- Your knowledge base changes frequently (product docs, support tickets, news)
- You need to cite specific sources or enable auditable answers
- You want to add domain knowledge without touching the model weights
- Speed of iteration matters — you can update knowledge without retraining
What is Fine-Tuning?
Fine-tuning adjusts the model’s weights on a curated dataset, teaching it new patterns, styles, or domain-specific knowledge it didn’t have from pre-training. The knowledge becomes part of the model itself. If you take this route with an open model, our QLoRA fine-tuning guide covers data preparation and training configuration.
Fine-tuning is the right choice when:
- You need the model to reliably follow a very specific output format or schema
- You want to teach a specific tone, style, or persona that must be consistent
- Your use case involves specialized domain knowledge not well represented in pre-training data
- Latency is critical and you can’t afford the overhead of RAG retrieval at inference time
The Hybrid Approach
In practice, the best production systems often use both. Fine-tune for style and format consistency, use RAG for up-to-date factual grounding. A customer support bot might be fine-tuned to always respond in a specific structured format, while using RAG to retrieve the latest product documentation.
Whichever you choose, measure it. Run both options against the same LLM evaluation framework before committing, and keep checking retrieval quality once it is live, as described in RAG reliability in production.
A Quick Decision Framework
| Question |
Points to RAG |
Points to Fine-tuning |
| Does the knowledge change often? |
✅ |
❌ |
| Do you need source attribution? |
✅ |
❌ |
| Do you need a specific output schema? |
❌ |
✅ |
| Do you have < 1000 high-quality examples? |
✅ |
❌ |
| Do you need sub-100ms inference? |
❌ |
✅ |
Both approaches require careful engineering to work well in production. If your team is evaluating which path to take, we’re happy to help you think through the architecture. Talk to Tensorplay about your LLM architecture.