Cost reduction is a systems problem
AI features that succeed tend to get expensive. Usage grows, prompts accumulate instructions, and every new workflow defaults to the most capable model because that was the one used in the prototype. The monthly bill then grows faster than the value it supports.
The durable fix is not a single model swap. It is understanding which workflows create value, then changing their model, prompt, retrieval, cache and infrastructure decisions without losing the quality users need. The goal is lower cost per successful outcome, not lower cost per token: a cheaper configuration that causes retries, manual clean-up or customer friction has simply moved the cost somewhere harder to see.
A worked example
This playbook grew out of a cost-reduction case study we originally published: a B2B SaaS company whose monthly LLM bill had reached $42,000 and was growing 30% month over month. Figures from that example appear throughout to show how the steps combine. Treat them as an illustration of the method, not a benchmark. Your savings depend entirely on your traffic, prompts and quality bar.
1. Instrument before you optimise
Do not change anything until you can see where the money goes. Log every LLM call with:
- the workflow or feature name, and the customer or tenant where appropriate;
- the model and inference configuration;
- input and output token counts;
- latency, errors and retries;
- a hash of the prompt template, so near-identical requests can be grouped;
- the user outcome, where you can capture one.
Aggregate cost by workflow, not just in total. That separates a genuinely expensive path from a noisy dashboard number, and it is the same observability the AI production readiness checklist asks for before launch. If you use API-hosted models, our OpenAI integration work covers the production controls involved: rate-limit handling, streaming, cost tracking and fallback behaviour.
In the worked example, 48 hours of this logging was enough to expose three problems:
- 34% of API calls were near-identical requests made within a 10-minute window;
- 22% of prompts were far more verbose than they needed to be;
- the most expensive model was being used for tasks a smaller, cheaper model handled just as well.
None of these would have been visible from the invoice.
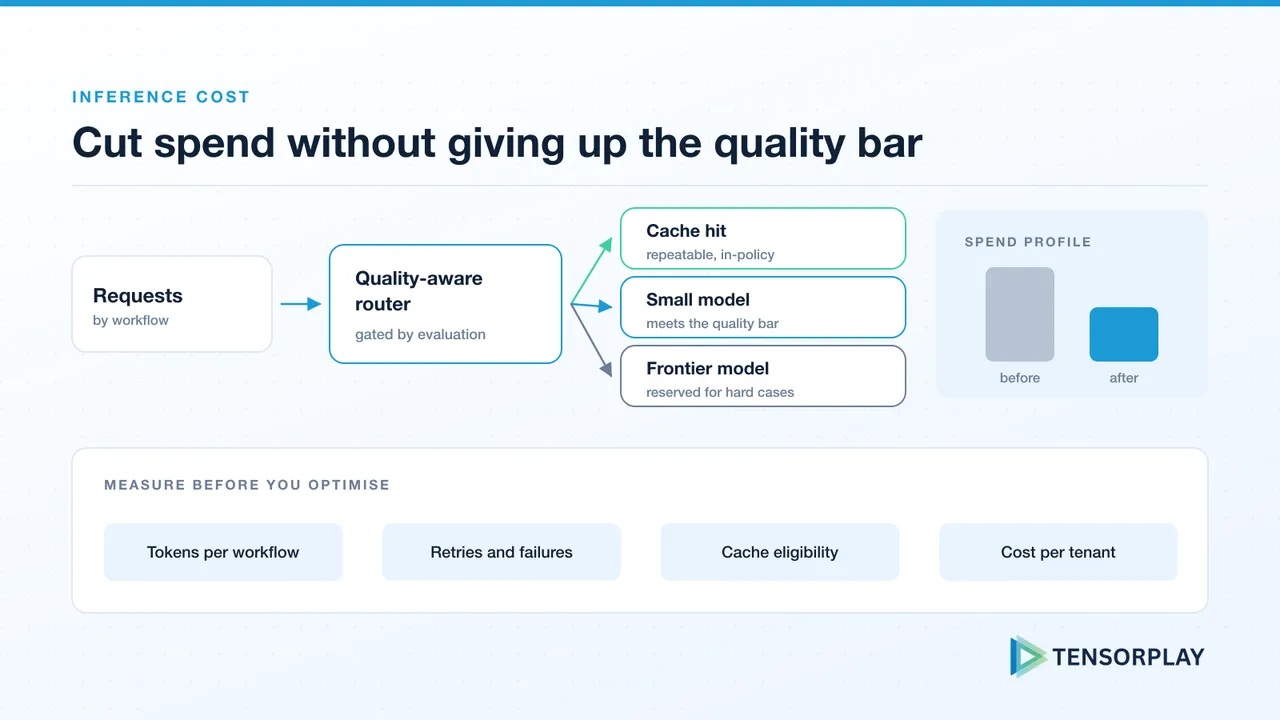
2. Route requests by measured quality
Not every task needs your most capable model. Extraction, classification, formatting and routing decisions usually have very different requirements from a customer-facing reasoning workflow.
Build an evaluation set for each task and find the cheapest model or configuration that meets its acceptance criteria. Then route: a lightweight classifier or a set of rules sends well-defined tasks to the smaller model and reserves the larger one for work where evaluation shows it changes the outcome. Keep a fallback to the next tier up when a response fails validation or the model refuses.
Routing without evaluation only shifts cost into errors, retries and manual clean-up, so use your LLM evaluation framework as the release gate for every routing change. In the worked example, each route was validated against 500 representative examples before it was deployed, and 55% of requests ended up on the cheaper model.
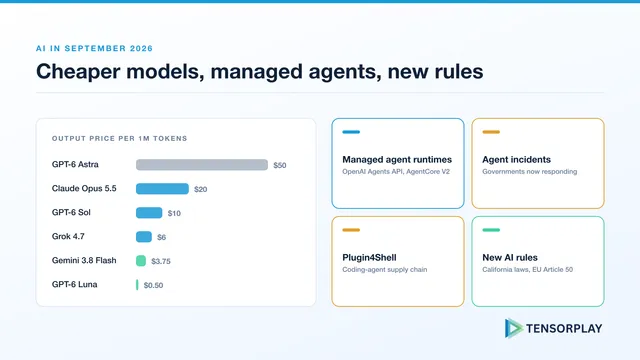
Routing is also where cost decisions age fastest. Cheaper model tiers improve every few months, so re-run the evaluation when new models ship. Our analysis of Gemini 3.8 Flash and tiered routing shows how quickly the right tier for a task can change.
3. Cache responses that are safe to reuse
Many applications answer the same question again and again. Two kinds of cache help:
- Exact caching keys on a normalised request and returns a stored response. It is simple and safe for deterministic, repeated calls.
- Semantic caching embeds the incoming query and checks whether a sufficiently similar question was answered recently. It catches paraphrases, which exact caching misses.
Semantic caching was the biggest single win in the worked example: for a FAQ-style support bot it removed 41% of API calls. The cache TTL was tuned per use case, shorter for dynamic data and longer for stable product documentation. A well-chosen vector store, such as Pinecone or one of the options in our vector database comparison, keeps lookups fast enough that the cache does not add noticeable latency.
Caching is also where cost work creates security and correctness bugs. Before reusing a response, check that:
- cache keys include the tenant and any permission scope, so one customer never receives another’s answer;
- expiry matches how quickly the underlying content changes;
- the similarity threshold is validated against your evaluation set, because two questions that look alike can need different answers;
- personalised or account-specific responses are excluded entirely.
4. Cut the tokens you do not need
Audit every system prompt. Prompts grow by accretion: redundant instructions, repeated examples and verbose formatting guides that were added to fix one bug and never removed. In the worked example the average system prompt was 847 tokens. A combination of manual editing and LLMLingua, a prompt compression technique from research, cut average prompt length by 38% with no measurable quality degradation on the evaluation suite.
Look beyond the system prompt too:
- Retrieved context: passing ten chunks when three answer the question means paying for seven you do not need. Tune retrieval depth against evaluation results.
- Conversation history: summarise or window older turns rather than resending the whole transcript.
- Output length: ask for the format you need and set a maximum output length that suits the task. Output tokens are usually priced higher than input tokens.
Prompt compression is a prompt change, so it should go through the same versioning and testing described in prompt engineering at scale.
5. Batch work that is not interactive
Not every request needs an answer in under a second. Document processing, nightly enrichment, report generation and evaluation runs can often be grouped and processed asynchronously. Batching improves throughput on self-hosted infrastructure, and several API providers offer batch endpoints at a lower price in exchange for slower turnaround. Separate interactive and background workloads early, so each can be optimised for what it actually needs.
6. Choose infrastructure for the traffic shape
For sustained, predictable or specialised workloads, self-hosted inference can beat API pricing, but only once utilisation is high enough to pay for the GPUs and the engineering time to run them. Our guide to GPU inference on a budget covers serving frameworks, quantisation, autoscaling and where the break-even point sits. Hugging Face supports model selection and deployment workflows, and AWS offers both managed and custom infrastructure options.
The right choice depends on traffic, latency requirements, operational capacity, data constraints and evaluation results. Many teams end up with a mix: API models for spiky or frontier-level work, and self-hosted models for high-volume, well-defined tasks.
What the combined changes looked like
Illustrative before-and-after figures from the worked example:
| Metric |
Before |
After |
| Monthly API cost |
$42,000 |
$16,400 |
| P95 latency |
3.2s |
1.1s |
| Cache hit rate |
0% |
41% |
| Quality score (eval) |
87% |
89% |
Two points are worth drawing out. Quality held, and moved slightly up, because every change went through evaluation first. And latency improved as a side effect: cached responses return almost immediately and smaller models are faster. Cost work done this way tends to improve the product rather than degrade it.
Keep costs from creeping back
Savings erode unless someone owns them:
- set a cost budget per workflow and alert when spend or tokens per request drift above it;
- review cost per successful outcome alongside quality in the same dashboard;
- re-forecast when providers change prices, using the standard price rather than an introductory rate;
- re-run routing evaluations when new model versions ship, in both directions: a cheaper model may now pass, or a pinned model may be deprecated.
If AI spend is growing faster than the product value it supports, talk to Tensorplay about an infrastructure and cost review.